Zanus AI NeuraMind
NeuraMind is an AI API running on our own servers in the United States. This is everything that happens between your request and its answer, and what's left afterwards.
Checking Measuring from you to our edge
How it works
One request, start to finish.
-
01 · Sent
Your app sends a request.
If your code already talks to an OpenAI-style API, change the base URL and the key and you're done. Same endpoints, same SDKs, same streaming.
OPENAI_BASE_URL=
  https://zanusneuramind.ai/api/v1
OPENAI_API_KEY=sk-zanus-…
-
02 · Checked
The key is checked at the edge.
Before your request goes anywhere, the edge confirms the key, the models it may use and how many requests it can run at once. A bad key stops here and never reaches the machine.
-
03 · Carried
It travels a private tunnel.
From the edge, the request goes through an encrypted tunnel to our servers in the United States. The machine has no public address; the tunnel is the only way in.
-
04 · Queued, fairly
It waits its turn, and so does everyone else.
When things get busy, capacity is split evenly between everyone with requests in flight, so no single heavy user can crowd out the rest. If a request waits longer than two minutes, you get a clear
429instead of a hang. -
05 · Thought
The machine thinks.
What it does today:
- Reasons step by step, as much or as little as you ask
- Reads images and video
- Calls your tools
- Answers in exactly the JSON shape you define, every time
- Streams its answer as it writes
This is the starting set.
AI-7700 · Zanus-owned Checking United States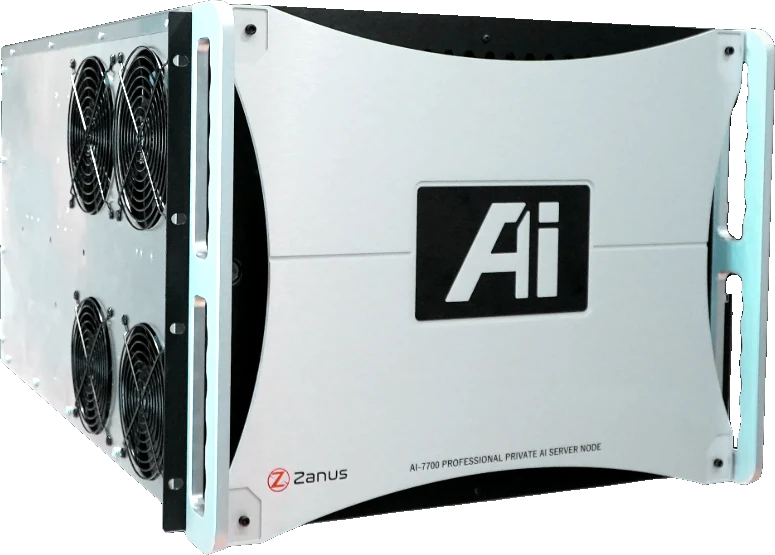
-
06 · Returned, and forgotten
The answer comes back. Nothing stays.
We record that a request happened: the model, the endpoint, the token count and how long it took. We never record what you asked or what came back. Nothing carries over between calls, so there's no stored conversation on our side to lose.
The details
Today's numbers. They'll move.
These are the limits right now.
- Context
- 64K tokens
- Images
- Up to 2 megapixels
- Video
- 2 frames per second, up to 64 frames
- Reasoning
- Off, low, medium, high
- Request size
- Up to 32 MB
- Endpoints
- Chat completions, responses, models, tokenize, detokenize
- Queue wait
- Up to 2 minutes, then
429